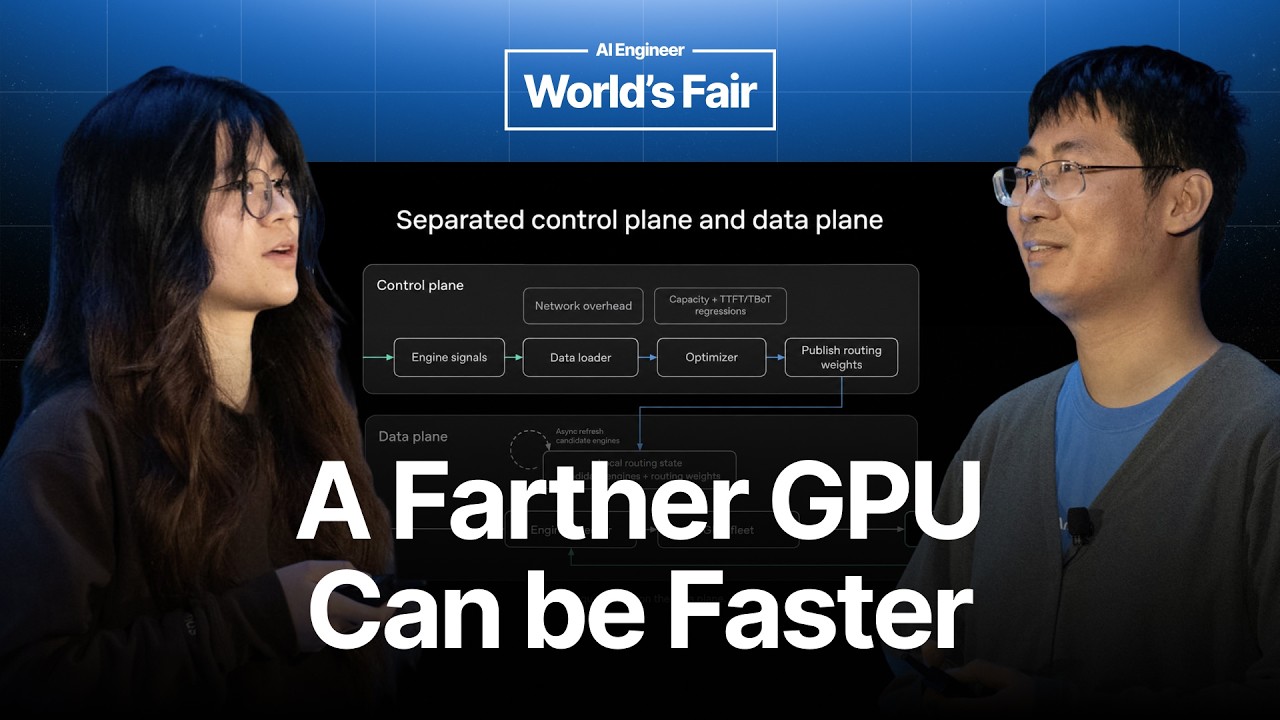
OpenAI replaced a feedback loop that adjusted routing weights with a control plane that computes explicit routing policies from a global view of CPU clusters and GPU engines.
2
The optimizer minimizes expected end-to-end latency by considering network distance, engine-side queueing, capacity, health, and latency profiles.
3
The system protects itself with outlier penalties, retry budgets that tighten under high utilization, and load shedding when demand exceeds capacity.
Summary
This talk explains how OpenAI routes inference requests across CPU gateway clusters and GPU engine clusters. The earlier system used weighted consistent hashing with weights produced by a proportional feedback controller. Engine signals such as time to first token, time between output tokens, and utilization were combined into a score, then compared with the fleet average. That adapted to changing conditions, but made individual routing decisions difficult to explain and could oscillate traffic between engines, damaging KV cache locality. The newer design separates a globally informed control plane from a fast data plane in each CPU cluster. The control plane turns demand, network latency, capacity, health, and latency profiles into routing-weight snapshots. The data plane uses a cached snapshot without waiting on the control plane. The optimizer accounts for both network distance and engine-side waiting, so a farther engine can be faster when a nearby engine is overloaded. Penalties, dynamic retry budgets, and load shedding handle failures and heavy load.
Inference routing must account for cache locality and changing engine conditions
The inference load balancer receives requests at CPU clusters and chooses among GPU engines that may be in different clusters, regions, or continents. Routing has to consider time to first token, time between output tokens, health, utilization, reliability, and KV cache locality. When a conversation's context is already cached on one engine, sending later turns there avoids recomputation and can reduce latency. This makes inference routing different from a basic request distributor.
Weighted consistent hashing started with weights from a proportional feedback loop
Early routing first removed engines that could not serve a request because of capability, compute, or data-residency constraints. It then used weighted consistent hashing to choose among the remaining engines. A periodic controller smoothed engine signals, computed a performance score, compared each engine with the fleet average, and raised or lowered its weight. The approach combined many signals into one decision and let engines with fewer constraints receive more traffic without constant manual tuning.
Feedback-driven weights were difficult to explain and tune
The adaptive controller had a serious cost: it was hard to explain why one engine received a higher weight than another. Tuning one property could affect other behavior because many signals were combined in the same loop. Different GPU skills and engine characteristics also made load distribution uneven. The system adapted, but engineers could not easily connect a routing outcome to a single reason.
Oscillation could destroy the cache locality that routing was meant to protect
When the controller shifted traffic away from a busy engine, that engine became cooler. The next signal then made it look able to accept more traffic, so the controller shifted traffic back. This back-and-forth could occur among a few engines and disrupt KV cache utilization. The problem motivated a design where signals inform an explicit policy instead of directly driving a constantly changing feedback loop.
A global control plane computes policy while local data planes answer requests
The new architecture gives the control plane a global view of CPU clusters and GPU engines. It computes globally optimized routing answers, while an engine selector in each CPU cluster makes the synchronous request decision from a locally cached snapshot. Candidate engines and routing weights refresh asynchronously. The data plane therefore does not wait for the control plane on every request, and separate signal and weight-update paths improve future decisions without slowing the request path.
Nearest-engine routing can lose to a farther engine with spare capacity
Geographic proximity is only one part of end-to-end latency. In the example, one cluster sends 120 requests per second to a nearby engine that can serve 100, while another engine farther away is handling 40 of its 80 requests per second. Sending the extra traffic to the farther engine adds network distance but avoids waiting behind an overloaded local engine. The farther destination can therefore produce a lower total latency.
The optimizer minimizes total latency under hard routing constraints
The optimizer takes demand from each CPU cluster, network latency to each engine, available capacity and health, and engine-side latency profiles for time to first token and time between output tokens. It produces the fraction of each cluster's traffic sent to each engine. Its objective is expected end-to-end latency, including network and engine-side latency. It must route all demand, keep engines within effective capacity, and keep weights non-negative.
Protection mechanisms reduce damage during failures and overload
Outlier penalties reduce an engine's routing weight and give it time to recover or be repaired. Retries are limited with budgets because additional retries during heavy utilization can create a retry storm. Those budgets are dynamic: the system can tolerate more retries during normal operation and fewer when utilization is high. Load shedding is the last resort, dropping part of the traffic so the whole system degrades rather than failing at once.
"The controller now thinks that this engine can take a lot more traffic. Then some traffic is going to be shifted back and forth between a few engines, disrupting the KV cache utilization."Qianru Lao07:05
Who should watch
You are designing an inference gateway that must choose among heterogeneous engines across clusters or regions.
Your current routing weights come from a feedback loop and are difficult to explain or tune.
You need practical safeguards for overload, retry storms, degraded engines, and capacity shortfalls.