latency
77 talks
 Judge a Transaction by the Company It Keeps
 Latency Is a Budget. Humanlike Is the Goal.
 Zero Cold Starts: Serverless AI Agents on Akamai Functions
 Is Speculative Decoding Worth It? Profiling vLLM on NVIDIA Blackwell
 What Is an Inference Engine, Anyway?
 Operating Distributed Inference Systems at Scale
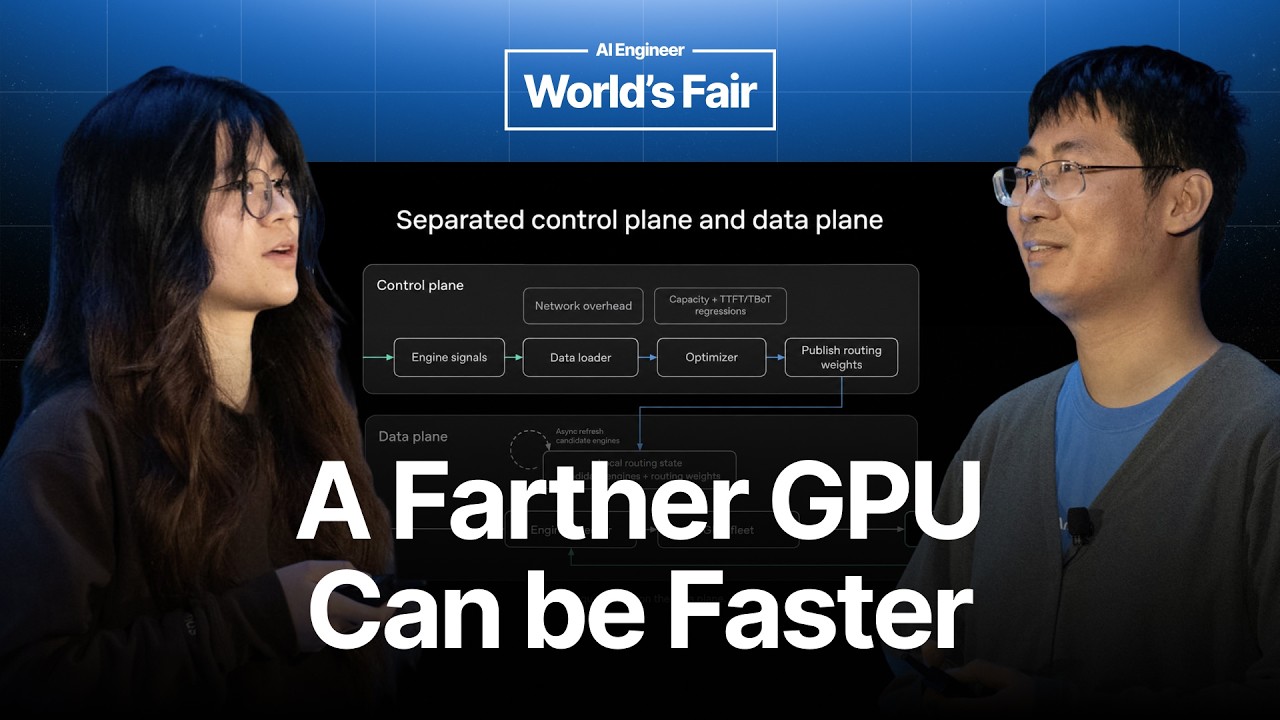 Routing LLM Inference in Production: From Engine Signals to Policy
 What's New in Inference Engineering
 Homa: The End of TCP for AI Clusters
 Connect AI to Billions of Legal Documents
 Where RL Will Take Search
 Your Agreements Are a Database You Can't Query
 5 Voice Agent Failure Modes You'll Hit in Week One
 Realtime Voice Agents with Frontier Intelligence
 Speech-to-Speech Model Research at Google DeepMind
 Tolan: Voice-First AI Companion
 Every step you take, every call you make: the reliable agent stack
 Deep dive on LLM Inference at Scale
 Agentic Sites: Building Hyper Personalized Websites
 Productionizing LLM Gateways: Architecture, Tradeoffs and Hard Lessons
 KV Cache-Aware Routing and P/D Disaggregation on Kubernetes
 Preferences Over Benchmarks: Model Routing
 From Ambient Documentation to Clinical Intelligence
 The Next Medium: Why Real-Time Interactive Video Changes Everything
 Let's integrate AI Agents in Event-Sourced Systems
 Serving 2 Million Models Without Melting: Scaling the Hugging Face Hub
 Agent Output Is Not UX: Rendering Layer Your LLM Pipeline Is Missing
 Designing Voice Agents for Real Conversations
 Don't Let the LLM Drive
 Your Voice Agent Doesn't Need a Frontier Model
 Frontier Results, On Device
 Browser Agents Don't Need Better Models. They Need Better Eyes.
 The 100-Tool Agent Is a Trap
 Voice In, Visuals Out: The Agony and the Ecstasy
 You Might Not Need 50 Diffusion Steps
 Under 5 minutes to a deployed LLM endpoint
 Text Diffusion
 Rethinking What State-of-the-Art Means
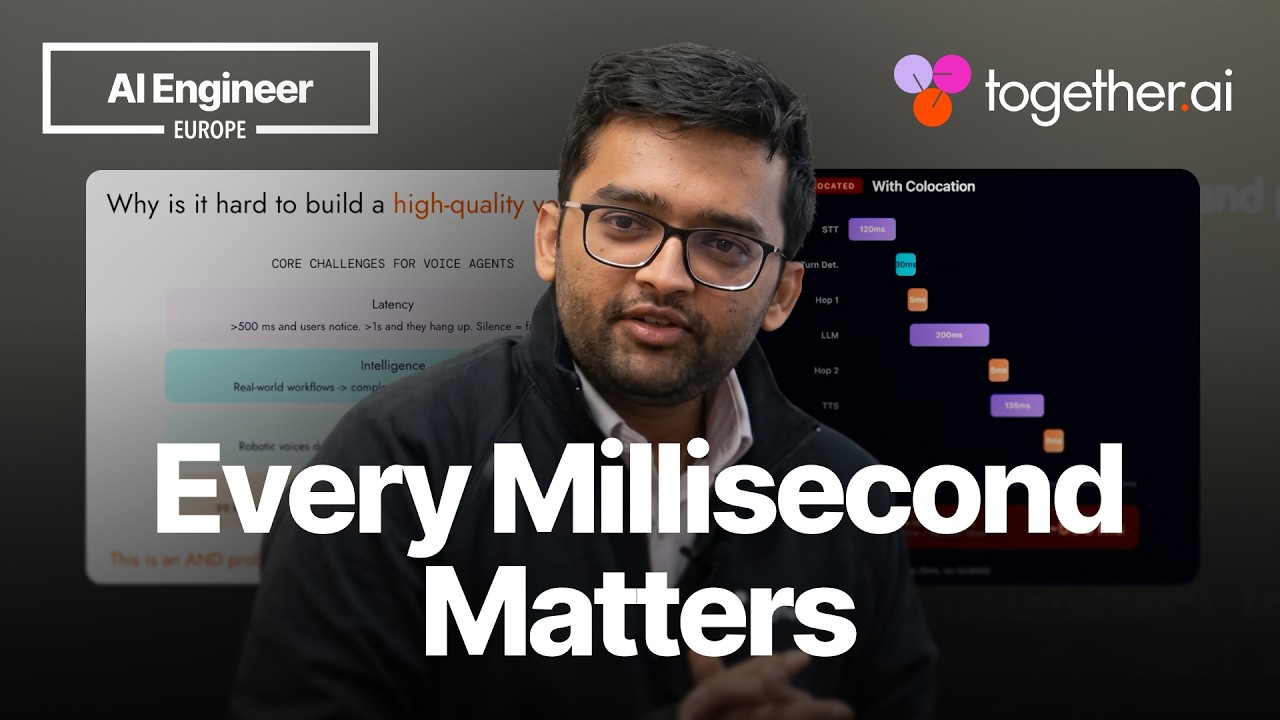 Engineering voice agents: Latency, quality, and scale
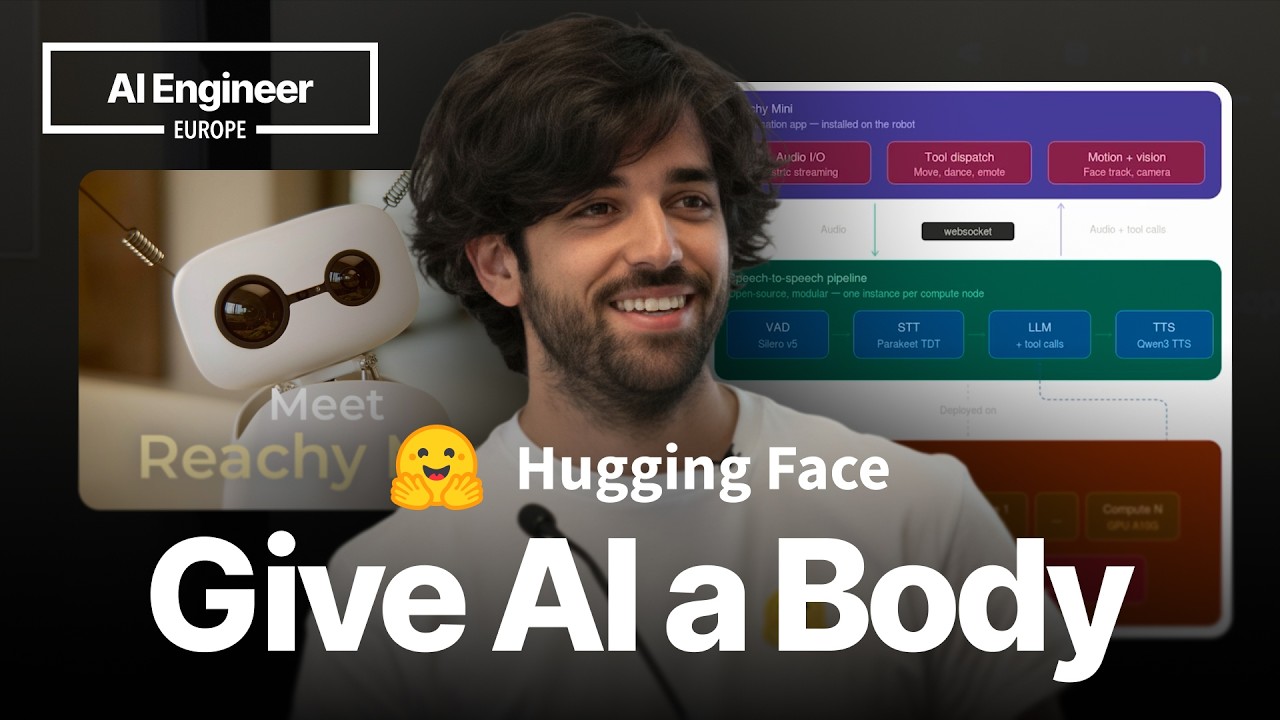 Reachy Mini: the $300 open source robot you can actually hack
 Building a Chess Coach
 Voice AI: When Is the "Her" Moment?
 Why TTS Models Now Look Like LLMs
 FLUX, Open Research, and the Future of Visual AI
 Running LLMs Locally: Practical LLM Performance on DGX Spark
 Coding Evals: From Code Snippets to Codebases
 Realtime Voice AI
 Hacking the Inference Pareto Frontier
 Pipecat Cloud: Enterprise Voice Agents Built On Open Source
 Serving Voice AI at $1/hr: Open-Source, LoRAs, Latency, Load Balancing
 Your realtime AI is ngmi
 Strategies for LLM Evals (GuideLLM, lm-eval-harness, OpenAI Evals Workshop)
 Introduction to LLM serving with SGLang
 HybridRAG: A Fusion of Graph and Vector Retrieval
 Good design hasn't changed with AI
 360Brew: LLM-based Personalized Ranking and Recommendation
 One Model to Rule Netflix Recommendations
 Optimizing Inference for Voice Models in Production
 From Mixture of Experts to Mixture of Agents with Super Fast Inference
 How fast are LLM inference engines anyway?
 Serving Voice AI at Scale
 The Eyes Are The (Context) Window to The Soul: How Windsurf Gets to Know You
 The Current State of Browser Agents
 The Voice-First AI Overlay: Designing Conversational Co-Pilots
 Finetuning: 500M AI Agents in Production with 2 Engineers
 The AI developer experience doesn't have to suck: why and how we built Modal
 Giving a Voice to AI Agents
 How to build the world's fastest voice bot
 Building an AI assistant that makes phone calls
 The GenAI Maturity Curve, or You Probably Don't Need Fine Tuning
 Llama 3 at 1,000 tok/s on the SambaNova AI Platform
 Substrate Launch: the API for modular AI
 A Practical Guide to Efficient AI
 Breaking AI's 1-GHz Barrier
 Building and Scaling an AI Agent Swarm of Low-Latency Real-Time Voice Bots
 How Codeium Breaks Through the Ceiling for Retrieval
 Storyteller: Building Multi-modal Apps with TypeScript and ModelFusion