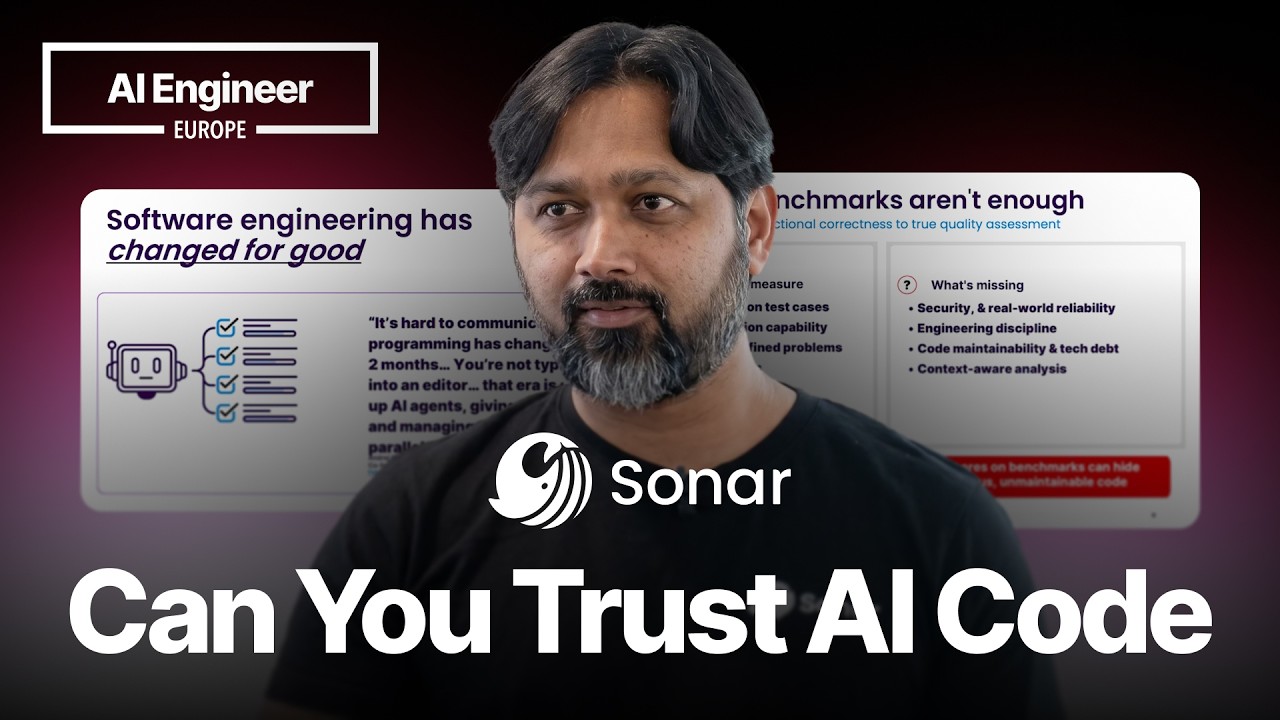
High functional pass rates do not show whether generated code is secure, maintainable, readable, or free of architectural problems.
2
Sonar evaluated more than 4,444 Java assignments across 53 models and found large differences in code volume, complexity, bugs, and security issues.
3
Sonar's ACDC framework guides code generation, verifies it before commit with SonarQube, and uses a remediation agent to fix issues while checking analysis and compilation results.
Summary
Prasenjit Sarkar argues that standard LLM coding benchmarks measure functional correctness while leaving out the properties that matter in an enterprise codebase. Sonar ran more than 4,444 Java assignments through 53 models and measured pass rate, lines of code, cyclomatic and cognitive complexity, bugs, and security issues. The results show that high-performing models can produce very different amounts of code and can introduce difficult-to-detect bugs or security problems. Sarkar attributes this to mixed-quality training data, hidden flaws in that data, probabilistic generation, limited context, and poor explainability. Sonar's response is the ACDC framework: guide the model with better context and data, verify generated code quickly before commit, then solve issues that reach a pull request. The remediation agent creates one fix per issue and checks each fix through analysis and compilation before presenting it to developers.
Agentic coding has moved English instructions into the programming workflow
Sarkar describes a shift from writing code directly in IDEs toward agentic coding platforms. Developers give instructions in English, let an agent generate code, and then review the result. He names tools and platforms including VS Code, JetBrains, Cursor, Windsurf, Antigravity, Codex, Claude, Devin, and Gemini CLI. He cites a March 2026 Pragmatic Engineer survey in which 55% of developers regularly used some AI agents. That adoption creates a practical question for teams: whether the generated code is maintainable, secure, and readable enough to trust.
Functional benchmarks leave out the engineering properties enterprises need
Sarkar separates benchmark pass rates from real-world code quality. HumanEval, MBPP, and SWE-bench mainly measure whether code works against test cases. They do not capture security, reliability in real use, architectural problems, engineering discipline, maintainability, technical debt, or context-aware analysis. Sonar built its evaluation around these missing dimensions. The point is that an 80% or higher pass rate does not tell a team whether the resulting code can be maintained safely inside its own codebase.
Sonar measured generated Java code across assignments and quality dimensions
Sonar evaluated more than 4,444 distinct Java programming assignments from open datasets and analyzed the generated code with SonarQube Enterprise. Sarkar says the evaluation produced data on functional performance, lines of code, complexity, bugs, and security issues. Sonar published the results in a public leaderboard covering more than 53 models and model versions. The leaderboard is intended to let teams compare models against the engineering properties that matter for their architecture, rather than choosing one from a single functional benchmark score.
Some high-performing models produce much more code and carry substantial security risk
Sarkar gives several examples from the evaluation. Gemini 3.1 Pro High had an 84.17% pass rate and produced 307,000 lines for the assignments, with a cyclomatic complexity of 234, 614 bugs per million lines, and 210 security issues per million lines. Claude Sonnet 4.6 produced 627,000 lines and had the highest security issue rate in the examples, at 300 per million lines. GPT 5.4 and GPT 5.4 Pro High produced 1.2 million lines for the same group of assignments. The comparison shows why pass rate alone is insufficient.
Training data, probabilistic generation, and limited context create hidden defects
Sarkar gives several reasons LLM-generated code can contain problems. Training data combines code of mixed quality, including examples with built-in security flaws. Subtle logic errors can also enter the training pool and later appear in generated code. Models are probabilistic, so the same prompt can produce different code at different times. They also lack knowledge of a company's codebase, data, and architecture unless that context is supplied. Sarkar adds that generated code is difficult to explain, which makes diagnosing and improving defects harder.
The leaderboard tracks both functional correctness and code characteristics
Sonar's leaderboard contains results for more than 53 models and different versions or configurations, including variations in reasoning effort. Sarkar says Gemini 3.1 Pro High had the highest pass rate in the displayed results, at 84.17%, and that five models exceeded 80% accuracy. The leaderboard also reports issue density, lines of code, cyclomatic complexity, and cognitive complexity. Sarkar presents it as a way to inspect the details for each model and choose one based on a team's architecture instead of relying on a single accuracy number.
Cognitive complexity measures how hard code is for people to maintain
Sarkar distinguishes cyclomatic complexity from cognitive complexity. Cyclomatic complexity counts branches and control-flow constructs such as if statements, else branches, for loops, and while loops. Sonar's cognitive complexity measure asks how difficult code is for a human to read, understand, and maintain. He says newer models tend to generate more lines of code, and some of those models also show higher cyclomatic and cognitive complexity. As models mature, total vulnerabilities may decrease while the remaining bugs and security issues become finer and harder for humans to detect.
ACDC puts guide, verify, and solve around the coding agent
Sonar's agent-centric development cycle is called ACDC. It has three stages: guide, verify, and solve, with an inner loop and an outer loop. The guide stage includes Sonar Context Augmentation and Sonar Sweep, which was in private beta during the talk. Context augmentation supplies the full codebase context to the LLM. Sonar Sweep is intended to treat problematic training or source data before it influences generated code. The verify stage uses SonarQube Agentic Analysis, and the solve stage uses the SonarQube Remediation Agent.
Fast pre-commit analysis catches issues before they enter a pull request
SonarQube Agentic Analysis runs through an MCP-enabled coding tool such as Claude, Codex, or Gemini CLI. After an agent generates code, the developer can ask for analysis before committing or pushing it to a pull request. Sarkar says this analysis takes 1 to 5 seconds, compared with 1 to 5 minutes for the CI analysis. The detected problems are sent back to the coding agent, which can fix them before the commit. The normal pull request analysis still runs afterward.
"Within 1 to 5 seconds the code which is being generated right now, before even commit, it will analyze and it will tell you that, oh, these are the problems that I found."12:18
Who should watch
You are selecting an LLM for production development and want evidence beyond benchmark pass rates.
Your team accepts generated code into pull requests but lacks checks for security, complexity, technical debt, or regressions.
You are evaluating agentic coding workflows and want a concrete pattern for adding context, fast analysis, and automated remediation.