testing
101 talks
 Rebuilding CI for AI-Scale Commit Volume
 Please... Enough with the Sloppy, One-Shot SaaS Replacements
 We Let Our Financial Planners Write the Agents
 AI Writes More PRs. Who Validates Them?
 Stop Prompting
 Your AI Agent Has No Nervous System
 AI Hackers Are Faster Than Your Pen Test
 Evals in AI: A Deep Dive
 From Vibes to Production: Evaluating and Shipping AI Agents That Work 101
 Why AI Didn't Actually Make You Ship Faster
 The Death of the Code Review: What the Data Actually Says
 AI-Generated Code Is Already Competing With Human Code
 How We Built an Agent That Improves Itself
 Are LLM Performance Benchmarks Reliable?
 5 Voice Agent Failure Modes You'll Hit in Week One
 I Monitored Crime Audio. Voice Agents Scare Me More.
 From AI-Assisted to AI-Native: Building a Frontier Development Team
 How to Get Your Org to Adopt Coding Agents (Without Shipping Garbage)
 Your Code Has Bugs. Lean4 Has Proofs: Formal Verification for Engineers
 Your Agent Evolved. Your Evals Didn't.
 AI is the World's Largest Relationship Therapist
 Shipping AI to a Million Patients Without an A/B Test
 How to Kill the Code Review
 Computer Use at the Edge of the Statistical Precipice
 Designing Agents (The Floor Is the Frontier)
 Guide, Verify, Solve
 When Will the Benchmaxxing Plague End?
 SimulationMaxxing: How We Ship Agents 20× Faster
 DeepSWE: A Contamination-Resistant Coding Benchmark
 From Agent Traces to Agent Simulations
 How Evals and Prompts Shape Agent Behavior
 Perception Agents
 Build Evals That Actually Matter
 Don't Ship Skills Without Evals
 Every Solo Agent Builder Eventually Reinvents a Worse Version of CI/CD
 Your agent is blindfolded
 The Pipeline Is Dead
 The Prompt is the Platform
 Your Agent Failed in Prod. Good Luck Reproducing It.
 BDD, ADR, PRD, WTF: Capturing Decisions for Humans and AI Alike
 Can LLMs Generate Enterprise Quality Code?
 Spec-Driven Testing for Agents With A Brain the Size of A Planet
 The maturity phases of running evals
 Why Rust is the Ideal Language for Vibe-Coding
 Fast Models Need Slow Developers
 Beyond Code Coverage: Functionality Testing with Playwright MCP
 Mind the Gap (In Your Agent Observability)
 Ship Real Agents: Hands-On Evals for Agentic Applications
 CI/CD Is Dead, Agents Need Continuous Compute and Computers
 Malleable Evals: Why Are We Evaluating Adaptive Systems with Static Tests?
 Feedback Loops are All You Need
 Full Walkthrough: Workflow for AI Coding
 Software Fundamentals Matter More Than Ever
 Shipping AI That Works: An Evaluation Framework for PMs
 Developer Experience in the Age of AI Coding Agents
 Making Codebases Agent Ready
 The 3 Pillars of Autonomy
 The State of AI Code Quality: Hype vs Reality
 The Cure for the Vibe Coding Hangover
 Vision: Zero Bugs
 Fuzzing in the GenAI Era
 Evals Are Not Unit Tests
 Vibe Coding with Confidence
 How to Improve Your Vibe Coding
 Practical Tactics to Build Reliable AI Apps
 From Self-driving to Autonomous Voice Agents
 Shipping Products When You Don't Know What They Can Do
 Beyond the Prototype: Using AI to Write High-Quality Code
 Devin 2.0 and the Future of SWE
 Rise of the AI Architect
 Build Dynamic Products, and Stop the AI Sideshow
 AI-powered entomology: Lessons from millions of AI code reviews
 How to Run Evals at Scale: Thinking Beyond Accuracy or Similarity
 Claude Code & the evolution of agentic coding
 The Build-Operate Divide: Bridging Product Vision and AI Operational Reality
 Mastering AI Evaluation: From Playground to Production
 Turning Fails into Features: Zapier's Hard-Won Eval Lessons
 Agentic Excellence: Mastering AI Agent Evals with Azure AI Evaluation SDK
 AI Red Teaming Agent: Azure AI Foundry
 CI in the Era of AI: From Unit Tests to Stochastic Evals
 Engineering Better Evals: Scalable LLM Evaluation Pipelines That Work
 Evals 101
 How to build world-class AI products
 To the moon! Navigating deep context in legacy code with Augment Agent
 Evals
 7 Habits of Highly Effective Generative AI Evaluations
 Agents reported thousands of bugs, how many were real?
 Building Reliable Support Agents Using the Effect TypeScript Library
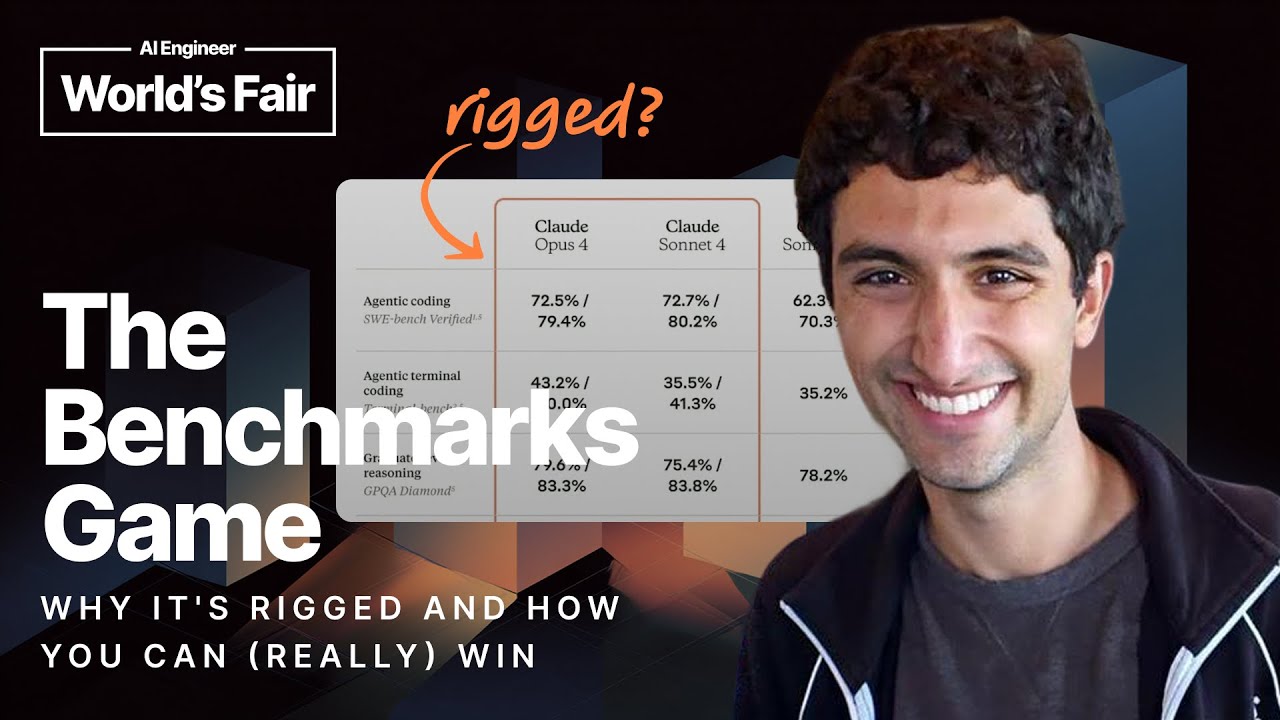 The Benchmarks Game: Why It's Rigged and How You Can (Really) Win
 Self Coding Agents
 Voice Agent Engineering
 The Agent Development Life Cycle
 Agent Evals: Finally, With The Map
 AI Agents, Meet Test Driven Development
 Your Evals Are Meaningless (And Here's How to Fix Them)
 Best Practices for Evaluating Large Language Model Applications with llmeval
 Enhancing Quality and Security in CI
 Iterating on LLM apps at scale: Learnings from Discord
 How Zapier Builds AI Products and Features with the Help of Braintrust
 How to Construct Domain Specific LLM Evaluation Systems
 Move Fast Break Nothing