Subjective tasks need a calibrated human evaluation process before teams build automatic evaluations around them.
2
LLM judges and task-specific rubrics can scale offline testing, but they must be checked against trusted human examples and statistical confidence signals.
3
A model should move from offline evaluation to human review, A/B testing, and production monitoring, with failures from production fed back into the other stages.
Summary
Cameron Wolfe presents a three-part evaluation process for AI tasks where quality cannot be checked with a deterministic function. Human evaluation comes first. Subject-matter experts define criteria and examples, then reviewers are calibrated by comparing their judgments and revising unclear guidelines. Statistical methods such as power analysis, error bars, and resampling help teams decide how much data they need and how much confidence to place in a result. Offline evaluation then uses LLM judges or task-specific rubrics as faster proxies for human review. Wolfe says these proxies should be compared with a trusted set of human-rated examples, with human agreement used as a reference point. Production monitoring and A/B tests provide another check through explicit feedback and behavioral signals such as abandonment. The process is cyclical: production failures become new evaluation examples, while successful offline ideas return to human review before deployment.
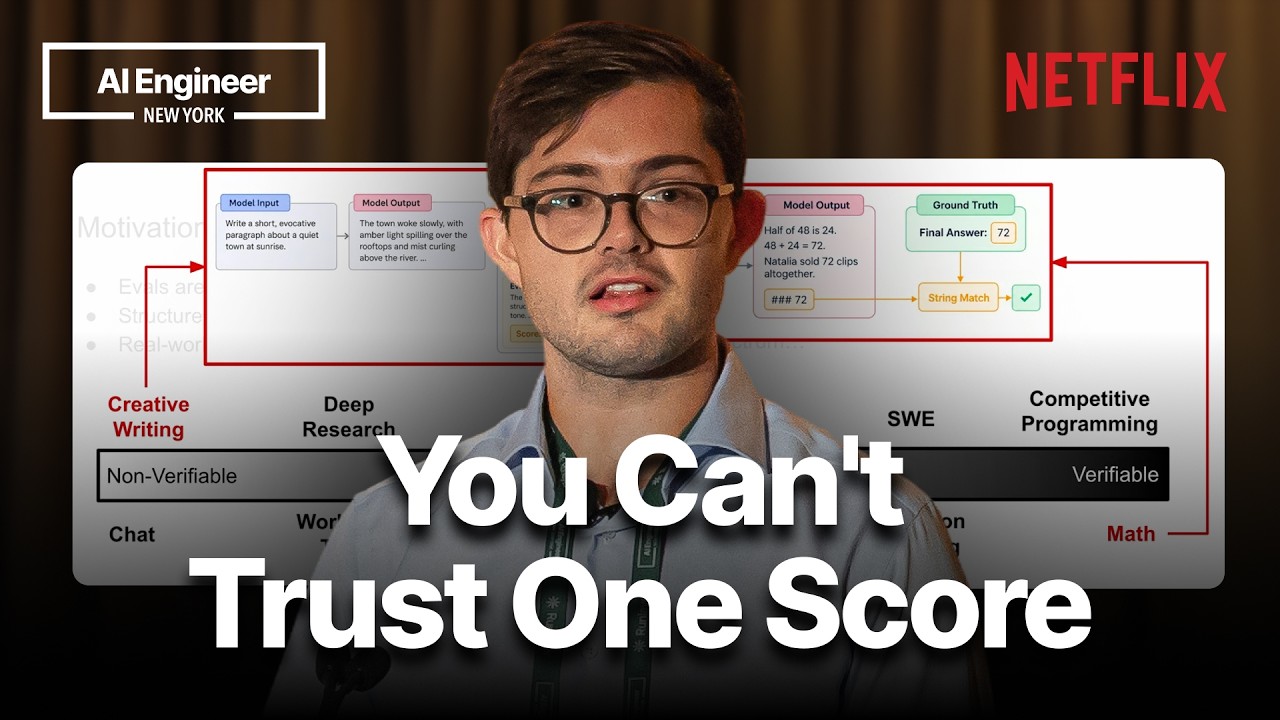
Wolfe says evaluation combines several non-deterministic components, including the agent and, for subjective tasks, the evaluator. Even verifiable benchmarks can be expensive, so teams often run them on relatively small task sets. That makes fluctuations harder to separate from real capability differences. In a typical trial, tasks go to an agent, the agent produces a solution, and a grader returns a pass or fail result. For tasks such as math, deterministic checks can work through string matching, symbolic verification, or test cases. Creative writing is different because people may disagree about whether an answer is good. Replacing a deterministic grader with an LLM judge adds another source of variation.
For a highly subjective task, Wolfe starts with human evaluation and calls it the North Star for defining, measuring, and improving quality. Subject-matter experts write guidelines that specify a small set of criteria, explain how to rate each one, and include detailed examples. Ratings might use binary or Likert scores. The goal is to give reviewers enough information to reduce avoidable subjectivity. Wolfe does not treat written guidelines as sufficient on their own. Teams should collect multiple judgments on the same data, inspect disagreements, and revise the guidelines when the source of disagreement is unclear wording or an incomplete definition.
Calibration requires repeated comparison between reviewers
Wolfe describes calibration as an iterative conversation with human reviewers. The team takes multiple evaluation samples for the same data and measures how often reviewers agree. When they disagree, the team asks whether the guideline makes the task unclear, then updates the instructions. This process continues until the criteria and examples support high agreement. A calibrated human process becomes the reference for later evaluation work. Wolfe also says teams need to sample evaluation data carefully. The set should reflect production tasks, contain problems that distinguish model capabilities, and be filtered for accuracy with model and human review.
Power analysis helps set the amount and type of evaluation data
Wolfe recommends power analysis to estimate how much data is needed to detect a meaningful difference between two models. The estimate depends on the effect size the team wants to detect, the noise in the results, and the desired significance level. Resampling model completions can help estimate that noise. Data selection also matters. Evaluation examples should be diverse and realistic, match the work done in production, and be difficult enough to distinguish models. Wolfe says these sampling principles apply to human evaluation and offline evaluation. A benchmark with too little or poorly chosen data can produce a result that looks precise while missing important behavior.
LLM judges and rubrics provide scalable offline proxies
Human review becomes a bottleneck when teams want to evaluate every new model or agent. Wolfe proposes automatic offline evaluations that use an LLM judge or a rubric as a proxy for human judgment. An LLM judge receives broad quality guidelines and applies them across tasks. A rubric is more specific: it defines a task-level checklist whose individual items are checked by an LLM judge. Wolfe cites the Dr. Tulu paper as an example involving cultural adaptation of a book into a Netflix film. Breaking quality into separate checks can make a subjective evaluation more concrete, but the result remains an imperfect automatic metric.
Because LLM judges and rubrics are proxies, Wolfe says teams should test whether they agree with trusted human evaluations. The comparison uses golden data, meaning human-rated examples whose quality the team considers reliable. Basic measures can include correlation and binary accuracy. There is no single agreement threshold that fits every task. More subjective tasks will generally produce lower agreement. Wolfe recommends comparing judge-human agreement with the agreement between humans themselves. He also describes a Netflix project in which an LLM judge's outputs were causally correlated with streaming metrics such as abandonment. When the judge rated something as bad, viewers were more likely to abandon the show after trying to watch it.
Statistics turn noisy scores into confidence signals
Offline evaluation has noise from both the model and the evaluator, so Wolfe recommends applying several statistical methods together. Power analysis can set the benchmark size. Error bars can show uncertainty around results. Resampling means taking multiple rollouts from the LLM or multiple evaluations from judges to reduce variance. The goal is to report scores with confidence signals rather than treating every score difference as meaningful. Wolfe says teams should also act on those signals by tightening them where possible. A higher score should be interpreted as a real capability improvement only when the difference is large and stable enough to be unlikely to come from evaluation noise.
Production monitoring completes the evaluation loop
A model that performs well offline still needs to be evaluated in production. Wolfe recommends tracking explicit signals such as thumbs-up and thumbs-down feedback or preference feedback, along with implicit signals such as session length and abandonment rate. A/B tests compare these measures with the existing system and can act as a soft deployment process before a full rollout. After deployment, monitoring can reveal performance trends and new failure cases. Those cases should return to the human and offline evaluation stages. Wolfe's process therefore keeps changing: guidelines can improve, reviewers and judges can be recalibrated, and production examples can become new benchmark data.