evals
376 talks
 AI Engineer NYC 2026
 How to Actually Tokenmaxx and Save Millions
 Deploying AI Inside a Bank Is Not an Engineering Problem
 The Agent Works. Does Anyone Trust It?
 Tokens Are the Cheap Part
 What Technical Due Diligence Finds When the Deck Says "70% Automated"
 Agents in Orbit: Workflows, Not Autopilot
 Build a Research Agent with Claude Managed Agents (Part 2 of 4)
 Claude Managed Agents Q&A: Evals, CI/CD and Multi-Tenancy (Part 4 of 4)
 Just-in-Time Ontologies: What Cheap Intelligence Means for Data
 Scheduled Agents, Dreaming and Q&A: Claude Managed Agents (Part 3 of 4)
 Latency Is a Budget. Humanlike Is the Goal.
 Parsing the Epstein Files for JMail
 Beyond RAG: A Relational Context Engine That Cuts Token Burn
 Small Models, Big Results: Training a Finance Agent for Under $500
 Why 80% Reliability Isn't Good Enough
 We Mapped 115 Microservices for Our Coding Agents
 Advanced Workshop: Mastering AI Observability
 The 6 Pillars of an Agentic Harness for Production
 The Self-Improving OSS Agent Stack
 Why Building an Eval Platform Is Harder Than It Looks
 Evals in AI: A Deep Dive
 From Vibes to Production: Evaluating and Shipping AI Agents That Work 201
 From Vibes to Production: Evaluating and Shipping AI Agents That Work 101
 The Transcript Looked Fine. The Call Wasn't.
 Your LLM Judge Is a Confident Liar: Building Better Verifiers
 Agents That Write Their Own Tools at Runtime
 How VS Code Went from Monthly to Weekly Releases with AI
 Your LLM App Returned 200 OK. It Was Still Wrong.
 Stop Rationing Tokens: Let the Harness Pick the Model
 The Death of the Code Review: What the Data Actually Says
 The State of AI in Software Development: Data from 400+ Orgs
 AI-Generated Code Is Already Competing With Human Code
 Scale the Judgment, Not the Model
 Autoresearch Made Our Models 3x Faster
 How We Built an Agent That Improves Itself
 Long-Horizon Agents Need Experiments, Not Just Prompts
 Teaching LLMs to Speak Spotify
 The Unreasonable Effectiveness of BM25 for Agentic Search
 A Linguistic Map for Voice Agents
 I Monitored Crime Audio. Voice Agents Scare Me More.
 Tokens Should Have Jobs
 Mousepower: agents that can't be measured, can't be managed
 Training Taste
 How long can your skills be before your agent forgets what you told it?
 Multimodal Collaborative Agents for Next-Gen Commerce
 SOTA Generative Media Panel
 Agents Are Where Microservices Were in 2015
 From Tokenmaxxing to Trusted Throughput
 The Half Life of Agent Infrastructure
 AI Evals for Cross-Functional Teams
 Building the Engine While Flying the Plane: Launching the Figma MCP Server
 Building uReview, Uber's Multi-Agent Code Review Engine
 How do you diffuse AI into the real world?
 The Agentic Commerce Stack
 Building GTM AI Agents: Lessons from Deploying to 6,000 Users
 The Death of Developer Advocates
 Preferences Over Benchmarks: Model Routing
 Prototyping as Leadership: How a CTO Ships with AI Agents
 Your Agent Evolved. Your Evals Didn't.
 200 Million Patient Interactions Later
 AI is the World's Largest Relationship Therapist
 Don't Be Data Poor
 From Ambient Documentation to Clinical Intelligence
 Guardrails First: Engineering Member-Facing Health AI
 Shipping AI to a Million Patients Without an A/B Test
 Trading Desks to Clinical Trials: Parallels in Applied Vertical AI
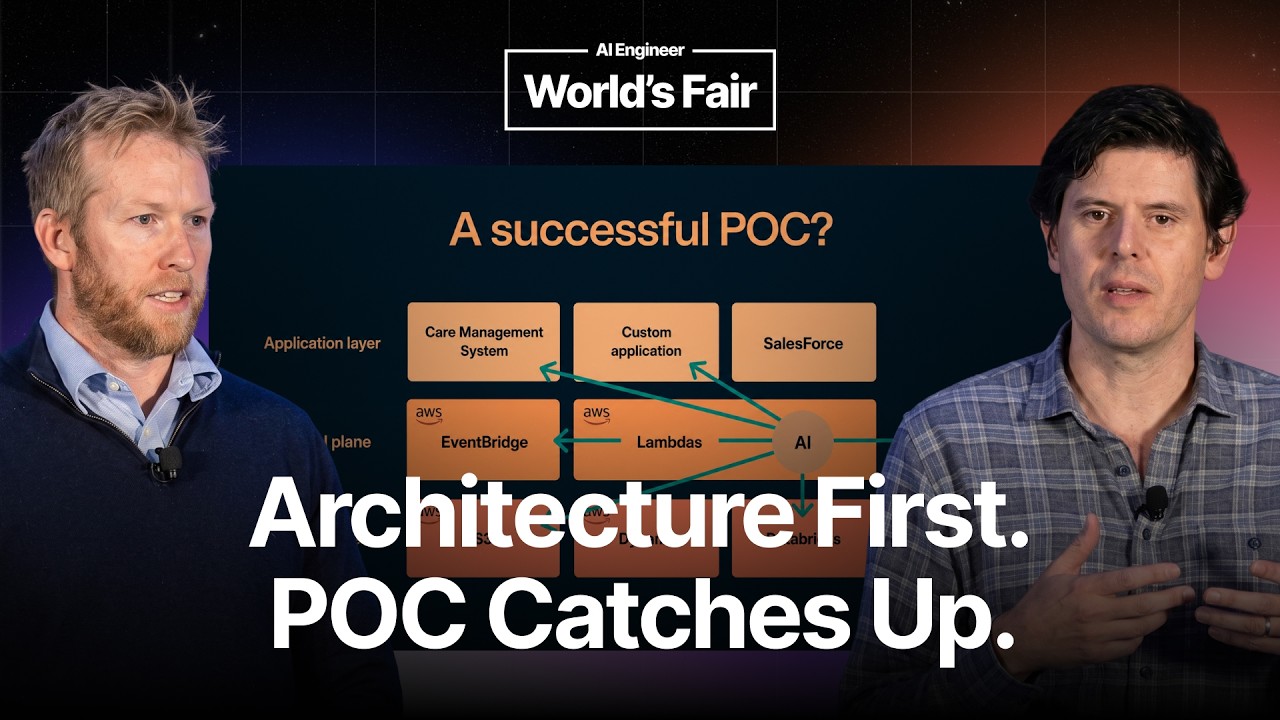 Why Your Enterprise Tech Stack Isn't Ready for AI Agents
 Context Engineering in 2026
 How to Kill the Code Review
 Computer Use at the Edge of the Statistical Precipice
 Beyond Static Intelligence: Evaluating Continual Learning
 Designing Agents (The Floor Is the Frontier)
 Memory Harnesses for Long-Running Research Agents
 Benchmarking Coding Agents on New vs Legacy Codebases
 Compression at the Edge
 When Will the Benchmaxxing Plague End?
 Rethinking Environments for Long-Horizon Work
 Teaching AI to Find Real Vulnerabilities
 Benchmarks: The Good, the Bad, and the Ugly
 Ending AI Slop
 Fighting Slop with Slop
 Reinforcement Learning without Verifiable Rewards
 Verifiable Environments for AI in Biology
 Morgan Stanley's ALPHALAB: Multi-Agent Research Across Optimization Domains
 Persona Engineering: A Field Guide to AI Synthetic Personas
 SimulationMaxxing: How We Ship Agents 20× Faster
 Skills are New Features: Building a Skill-Centric Harness
 How Forward Deployed Engineering is done at Ramp
 DeepSWE: A Contamination-Resistant Coding Benchmark
 Evaling Video Slop
 Evals-Driven Development for a Mental Health AI Coach
 From Agent Traces to Agent Simulations
 Building Closed-Loop Evals for a Multimodal Agent at Scale
 Everything Is a Rollout
 How Evals and Prompts Shape Agent Behavior
 The Future of Evals: From LLM as a Judge to Agent as a Judge
 Training Frontier Models to Out-Think Hackers
 Vending-Bench: Long-Horizon Agent Evals
 Harness Engineering is Not Enough: Why Software Factories Fail
 The Unreasonable Effectiveness of Separating the Task from the Model
 Active Graph Agent Runtime (BabyAGI 4)
 Claude for Long-Horizon Tasks
 Your Moat Is Your Data Model
 The Biggest Challenge in Your Stack? Evals, Evals, Evals
 Enterprise Agents Have a Structure Problem
 In the Land of AI Agents, the Verifiers Are King
 Medic for Apache Spark: First Aid for Failing Jobs
 Through the AI Fog: The Architectural Decision Agentic Security Depends On
 Why Your Agent Disagrees With Itself (And What To Do About It)
 Build Evals That Actually Matter
 Stop Burning Tokens: Why Self-Improvement Needs Domain Expertise First
 Your Agents Need a Save Button
 On AI and Knowledge
 Software engineering is not about writing code
 The Great Loops Debate
 How Autoresearch Is Changing ML Research
 Claude Fable, Claude Tag, and Anthropic's Culture
 Recursive Model Improvement
 Don't Ship Skills Without Evals
 Modern Post-Training: A Deep Dive
 Stop Evaluating Models Like It's the 50s
 ReviewDebt: A Practical Framework for Scoring Every Pull Request
 What Does Done Even Mean? Agents and Paperclip's Liveness Model
 Should AI Engineers Still Read Code in 2026? The Z/L Continuum
 Teaching Coding Agents to Do Spreadsheets
 Your coding agent doesn't always follow your rules
 Your LLM Deception Monitor Is Broken. The Fix Is in the Training Data
 Build AI Systems for Discernment, Not Approval
 Respect The Process
 SWE-Marathon: Evaluating Coding Agents at Billion-Token Scale
 Continual Learning for AI Agents: From Failures to Durable Improvements
 The Missing Layer After Launch
 Harness Engineering & Startup Battlefield
 Autoresearch & Keynotes
 Software Factories & Keynotes
 Frontier Results, On Device
 The Agentic AI Engineer
 Your Agent Failed in Prod. Good Luck Reproducing It.
 Agents Building Agents
 AI System Design: From Idea to Production
 User Signal Dies at the Retrieval Boundary
 Agents in Production: How OpenGov Built and Scaled OG Assist
 Production Evals For Agentic AI Systems
 The Miranda Hypothesis: How Hamilton Poisoned Persona Evals
 The Production AI Playbook: Deploying Agents at Enterprise Scale
 Why Can't Anyone Answer Questions About the Business?
 Your Attention Is the Bottleneck, Not Your Agents
 Self Driving Products: Product Signals to Pull Requests
 Stop Making Models Bigger, Make Them Behave
 LLM Observability, Evaluation, Experimentation Platform
 Evals Are Broken, Use Them Anyway
 Beyond Transcription: Building Voice AI That Understands Conversations
 Dark Factory: OpenClaw Ships Faster Than You Can Read the Diff
 SWE-rebench: Lessons from Evaluating Coding Agents
 The Art & Science of Benchmarking Agents
 How Lovable self-improves every hour
 Task Fidelity Scaling Laws
 Rethinking What State-of-the-Art Means
 Can LLMs Generate Enterprise Quality Code?
 Spec-Driven Testing for Agents With A Brain the Size of A Planet
 How I Deleted 95% of My Agent Skills and Got Better Results
 How We Built Zeta2: Training an Edit Prediction Model in Production
 Why (Senior) Engineers Struggle to Build AI Agents
 How Agent Observability Differs from Traditional Observability
 The maturity phases of running evals
 Agentic Evaluations at Scale, For Everybody
 Does GenAI "belong" to data scientists?
 Skill issue: Lessons from skilling up coding agents to use Langfuse
 Build Agents That Run for Hours
 AI Engineer Singapore Day 2
 Fighting AI with AI
 AIE Singapore Day 1
 How to Leverage Domain Expertise
 Combine Skills and MCP to Close the Context Gap
 Mind the Gap (In Your Agent Observability)
 Ship Real Agents: Hands-On Evals for Agentic Applications
 Building a Chess Coach
 Lessons from Trillion Token Deployments at Fortune 500s
 Malleable Evals: Why Are We Evaluating Adaptive Systems with Static Tests?
 How We Solved Context Management in Agents
 Agent Optimization with Pydantic AI: GEPA, Evals, Feedback Loops
 Everything You Need To Know About Agent Observability
 Full Walkthrough: Writing & Using Skills
 The Multi-Agent Architecture That Actually Ships
 Skill Issue: How We Used AI to Make Agents Actually Good at Supabase
 Context Is the New Code
 Shipping complex AI applications
 Replacing 12K LoC with a 200 LoC Skill
 Why building eval platforms is hard
 What Do Models Still Suck At?
 Build Your Own Deep Research Agents
 AIE Europe Keynotes & Coding Agents
 Judge the Judge: Building LLM Evaluators That Actually Work with GEPA
 Let LLMs Wander: Engineering RL Environments
 How METR Measures Long Tasks and Experienced Open Source Developer Productivity
 Build a Prompt Learning Loop
 Shipping AI That Works: An Evaluation Framework for PMs
 Why Agent Hype Can Fall Short of Reality
 The Unreasonable Effectiveness of Prompt Learning
 From Arc to Dia: Lessons Learned Building AI Browsers
 Leadership in AI Assisted Engineering
 AI Kernel Generation: What's Working, What's Not, What's Next
 Your Support Team Should Ship Code
 Coding Evals: From Code Snippets to Codebases
 Can You Prove AI ROI in Software Engineering?
 The State of AI Code Quality: Hype vs Reality
 Agent Reinforcement Fine-Tuning
 RL Environments at Scale
 Agents are Robots Too: What Self-Driving Taught Me About Building Agents
 From Stateless Nightmares to Durable Agents
 AI Engineer Code Summit 2025
 AI Leadership
 Building an Agentic Platform
 Five hard earned lessons about Evals
 Perceptual Evaluations: Evals for Aesthetics
 Fuzzing in the GenAI Era
 Multi Agent AI and Network Knowledge Graphs for Change
 Designing AI-Intensive Applications
 The Future of Evals
 2025 is the Year of Evals! Just like 2024, and 2023, and …
 Evals Are Not Unit Tests
 How to Look at Your Data
 On Engineering AI Systems that Endure the Bitter Lesson
 How to Improve Your Vibe Coding
 Practical Tactics to Build Reliable AI Apps
 Useful General Intelligence
 The 2025 AI Engineering Report
 From Self-driving to Autonomous Voice Agents
 Building Metrics that Actually Work
 Evaluating AI Search: A Practical Framework for Augmented AI Systems
 Layering Every Technique in RAG, One Query at a Time
 Scaling Enterprise-Grade RAG: Lessons from Legal Frontier
 Make Your LLM App a Domain Expert: How to Build an Expert System
 Shipping Products When You Don't Know What They Can Do
 Why Your Product Needs an AI Product Manager, and Why It Should Be You
 Information Retrieval from the Ground Up
 Strategies for LLM Evals (GuideLLM, lm-eval-harness, OpenAI Evals Workshop)
 Waymo's EMMA: Teaching Cars to Think
 Human seeded Evals
 Your Coding Agent Just Got Cloned And Your Brain Isn't Ready
 Building AI Products That Actually Work
 Building Applications with AI Agents
 Rise of the AI Architect
 Build Dynamic Products, and Stop the AI Sideshow
 Does AI Actually Boost Developer Productivity? (100k Devs Study)
 From Copilot to Colleague: Trustworthy Agents for High-Stakes
 How Intuit Uses LLMs to Explain Taxes to Millions of Taxpayers
 How to Build Planning Agents without Losing Control
 POC to PROD: Hard Lessons from 200+ Enterprise GenAI Deployments
 AI-powered entomology: Lessons from millions of AI code reviews
 How to Run Evals at Scale: Thinking Beyond Accuracy or Similarity
 HybridRAG: A Fusion of Graph and Vector Retrieval
 UX Design Principles for Semi Autonomous Multi Agent Systems
 Building Effective Voice Agents
 Google Photos Magic Editor: GenAI Under the Hood of a Billion-User App
 How to Train Your Agent: Building Reliable Agents with RL
 OpenThoughts: Data Recipes for Reasoning Models
 Shipping an Enterprise Voice AI Agent in 100 Days
 Measuring AGI: Interactive Reasoning Benchmarks for ARC-AGI-3
 Transforming search and discovery using LLMs
 Benchmarks Are Memes: How What We Measure Shapes AI and Us
 Prompt Engineering and AI Red Teaming
 The New Code
 The Wild World of AI: 6 Months That Changed Everything
 2025 in LLMs so far, illustrated by Pelicans on Bicycles
 Training Agentic Reasoners
 The Build-Operate Divide: Bridging Product Vision and AI Operational Reality
 Mastering AI Evaluation: From Playground to Production
 Turning Fails into Features: Zapier's Hard-Won Eval Lessons
 Agentic Excellence: Mastering AI Agent Evals with Azure AI Evaluation SDK
 AI Red Teaming Agent: Azure AI Foundry
 CI in the Era of AI: From Unit Tests to Stochastic Evals
 Data is Your Differentiator: Building Secure and Tailored AI Systems
 Engineering Better Evals: Scalable LLM Evaluation Pipelines That Work
 Evals 101
 Forget RAG Pipelines: Build Production-Ready Agents in 15 Minutes
 Graph Intelligence: Enhance Reasoning and Retrieval Using Graph Analytics
 GraphRAG methods to create optimized LLM context windows for Retrieval
 How to build world-class AI products
 Prompt Engineering is Dead
 Taming Rogue AI Agents with Observability-Driven Evaluation
 Vector Search Benchmark[eting]
 Why should anyone care about Evals?
 RFT, DPO, SFT: Fine-tuning with OpenAI
 Windsurf everywhere, doing everything, all at once
 Case Study + Deep Dive: Telemedicine Support Agents with LangGraph/MCP
 How to Build Trustworthy AI
 Break It 'Til You Make It: Building the Self-Improving Stack for AI Agents
 AI Engineer World's Fair 2025, Day 2 Keynotes & SWE Agents Track
 Evals
 Reasoning + RL
 Retrieval + Search
 Tiny Teams
 GraphRAG
 7 Habits of Highly Effective Generative AI Evaluations
 Agents reported thousands of bugs, how many were real?
 Buy Now, Maybe Pay Later: Dealing with Prompt-Tax While Staying at the Frontier
 Effective AI Agents Need Data Flywheels, Not The Next Biggest LLM
 Grounded Reasoning Systems for Cloud Architecture
 Invisible Users, Invisible Interfaces: Accelerating Design Iteration with AI Simulation
 open-rag-eval: RAG Evaluation without "golden" answers
 RAG Evaluation Is Broken! Here's Why (And How to Fix It)
 The Benchmarks Game: Why It's Rigged and How You Can (Really) Win
 The Coherence Trap: Why LLMs Feel Smart (But Aren't Thinking)
 The Current State of Browser Agents
 The RAG Stack We Landed On After 37 Fails
 Will Agent Evaluation via MCP Stabilize Agent Networks?
 Ensure AI Agents Work: Evaluation Frameworks for Scaling Success
 Evaluating Domain-Specific LLMs for Real-World Finance
 The DevOps Engineer Who Never Sleeps
 AI + Security & Safety
 Building and evaluating AI Agents
 Anthropic in the Enterprise
 How to Fail at AI Strategy
 The Agent Development Life Cycle
 Building AI Agents with Real ROI in the Enterprise SDLC
 AI Engineering at Jane Street
 Navigating AI's Frontier in 2025
 Reinforcement Learning for Agents
 Agent Evals: Finally, With The Map
 AI Agents, Meet Test Driven Development
 Building Enterprise LLM Agents That Work
 How Coding Agents Change Software Development Forever
 Lessons from building GenAI based applications
 Mission-Critical Evals at Scale
 Voice Agents: the good, the bad, and the ugly
 Your Evals Are Meaningless (And Here's How to Fix Them)
 Agent Engineering (Day 2)
 AI Leadership
 Optimizing LLMs in Insurance with DSPy
 The GenAI Maturity Curve, or You Probably Don't Need Fine Tuning
 Insights from Snorkel AI Running Azure AI Infrastructure
 LLM Quality Optimization Bootcamp
 Build, Evaluate and Deploy a RAG-Based Retail Copilot with Azure AI
 Creating and scaling your own custom copilots with Azure AI Studio
 Lessons from the Trenches: Building LLM Evals That Work IRL
 Multi model multimodal and multi agent innovations in Azure AI
 Best Practices for Evaluating Large Language Model Applications with llmeval
 BotDojo Launch: Enhancing AI Assistants with Evaluations and Synthetic Data
 How to Evaluate a Model for Your Use Case
 Scaling AI in Education: A Khanmigo Case Study
 AI Platform Engineering
 E-Values: Evaluating the Values of AI
 Hiring & Building an AI Engineering Team
 RAG for VPs of AI
 Real ROI: Lessons from Enterprises That Have Already Succeeded with LLMs at Scale
 The ROI of AI: Why You Need an Eval Framework
 Understanding AI Stakes to Break Production Code
 Iterating on LLM apps at scale: Learnings from Discord
 Navigating RAG Optimization with an Evaluation Driven Compass
 How Zapier Builds AI Products and Features with the Help of Braintrust
 What It Actually Takes to Deploy GenAI Applications to Enterprises
 Productionizing GenAI Models
 Architecting and Testing Controllable Agents
 How to Construct Domain Specific LLM Evaluation Systems
 Judging LLMs
 Building with Anthropic Claude: Prompt Workshop
 Running AI Applications in Minutes with AI Templates
 How Codeium Breaks Through the Ceiling for Retrieval
 Lessons From A Year Building With LLMs
 Keynotes & Multimodality Track
 How to Become an AI Engineer from a Fullstack Background
 Trust, but Verify
 Building Production-Ready RAG Applications
 Domain adaptation and fine-tuning for domain-specific LLMs
 AI Engineering 201: The Rest of the Owl
 Move Fast Break Nothing
 The AI Evolution
 The AI Pivot
 Building Blocks for LLM Systems & Products
 Building Context-Aware Reasoning Applications with LangChain and LangSmith
 The Future of Work
 Principles for Prompt Engineering
 AI Engineer Summit 2023, Day 2 Livestream
 AI Engineer Summit 2023, Day 1 Livestream