multimodal
126 talks
 From 15% to 90% GPU Utilization: Fix the Data Pipeline, Not the Model
 How MiniMax M3 Was Built: Sparse Attention and Native Multimodality
 Grep or Embeddings? Agentic Search Over Company Documents
 An Interaction Is All You Need
 I Gave an AI a Body
 From VLM/VLAs to Embodied Agents
 Your Agreements Are a Database You Can't Query
 Speech-to-Speech Model Research at Google DeepMind
 Voice Agents Can Just Do Things
 Your Voice Agent is Just a Walkie Talkie
 One Designer + AI. Hundreds of Deliverables.
 Why AI Agents Need Million-Token Context
 Multimodal Collaborative Agents for Next-Gen Commerce
 SOTA Generative Media Panel
 Building the Engine While Flying the Plane: Launching the Figma MCP Server
 Building an Agentic Video Editor for Mass Consumer
 Generative Video at the Speed of Light
 The Next Medium: Why Real-Time Interactive Video Changes Everything
 Voice agents with Realtime Video
 While My Guitar Gently Speaks
 Computer-use models will agentify the web, not APIs
 The Dark Arts of Web Automation: Teaching Agents to Use Websites Like Humans
 The New Primitives: Building AI Native Software
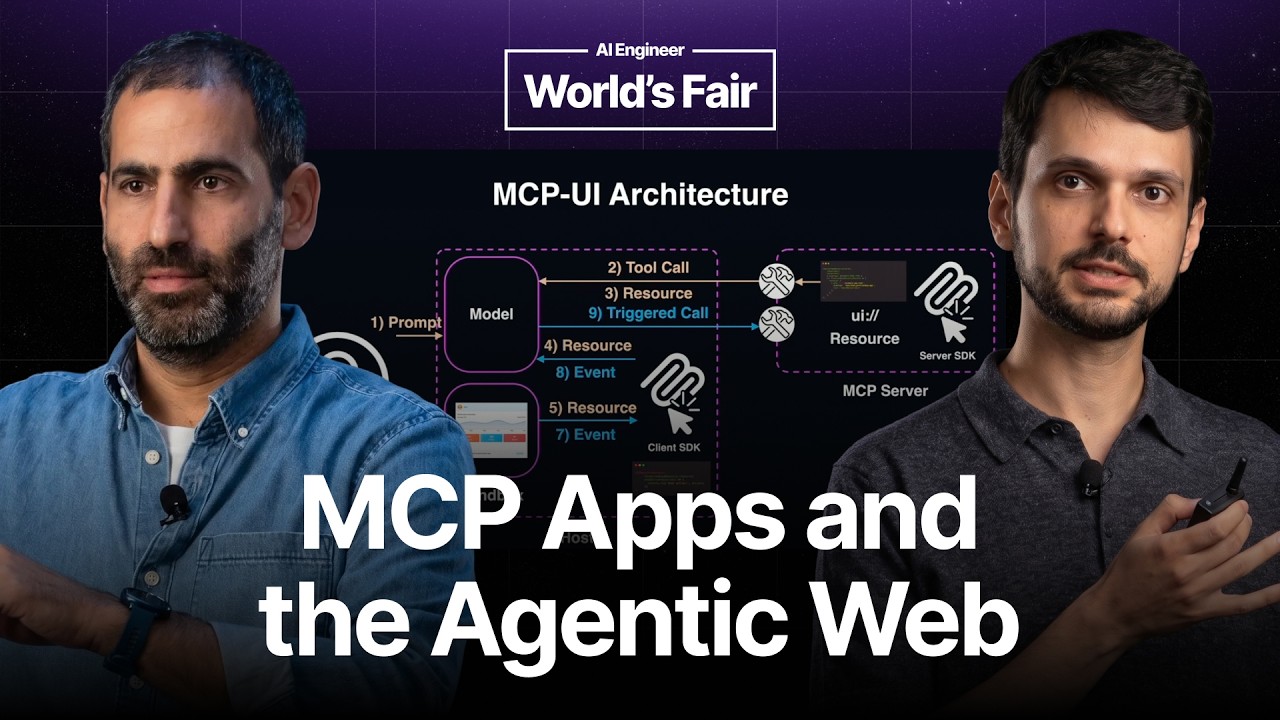 MCP Apps: Extending the Frontier
 Agents at Scale: Inside MiniMax's Model and the Infrastructure Behind It
 Evaling Video Slop
 Building Closed-Loop Evals for a Multimodal Agent at Scale
 Local Agentic Theory For Mobile Games
 Perception Agents
 Video Has No Memory. Here's How We Built One.
 HTML Is All Agents Need
 From Tokens to Cells: Foundation Models for Single-Cell Biology
 Autonomous Agents for Scientific Tasks
 Running a Chess YouTube Channel Entirely by AI
 Think You Can Build a Game with AI? Think Again!
 MCP Apps: Primitives, Discovery, and the Future of Software
 HTML is All You Need (for Agents to Make Graphics)
 OpenClaw in Your Hand: Building a Physical AI Terminal
 Voice In, Visuals Out: The Agony and the Ecstasy
 From Transcription to Live Music: Gemini's Audio Stack
 GPU Cloud Deployment Without Leaving Your IDE
 Building Interactive UIs in VS Code with MCP Apps
 Beyond Transcription: Building Voice AI That Understands Conversations
 Beyond Components: Designing Generative UI for MCP Apps
 How to Talk to Statues
 Prompt to Pipeline: Building with Google's Gen Media Stack
 Any-to-Any: Building Native Multimodal Agents
 Let's Go Bananas with GenMedia
 Why MLX
 FLUX, Open Research, and the Future of Visual AI
 How Transformers Finally Ate Vision
 Training an LLM from Scratch, Locally
 Building Conversational Agents
 Build & deploy AI-powered apps
 Gemma 4 Deep Dive
 Building Generative Image & Video Models at Scale
 Gemma, DeepMind's Family of Open Models
 How Google DeepMind Is Researching the Next Frontier of AI for Gemini
 AI Didn't Kill the Web, It Moved in!
 Building Intelligent Research Agents with Manus
 Building in the Gemini Era
 VoiceVision RAG: Integrating Visual Document Intelligence with Voice Response
 Defying Gravity
 Z.ai GLM 4.6: What We Learned From 100 Million Open Source Downloads
 Building an Agentic Platform
 Perceptual Evaluations: Evals for Aesthetics
 Vision AI in 2025
 Real-time Experiments with an AI Co-Scientist
 What Is a Humanoid Foundation Model? An Introduction to GR00T N1
 Why you should care about AI interpretability
 Robotics: why now?
 Waymo's EMMA: Teaching Cars to Think
 Rise of the AI Architect
 Books reimagined: AI to create new experiences for things you know
 tldraw.computer
 Robots as Professional Chefs
 ComfyUI Full Workshop
 Google Photos Magic Editor: GenAI Under the Hood of a Billion-User App
 On Curiosity
 Teaching Gemini to Speak YouTube: Adapting LLMs for Video Recommendations to 2B+DAU
 The State of Generative Media
 What We Learned from Using LLMs in Pinterest
 AI Engineering with the Google Gemini 2.5 Model Family
 A year of Gemini progress + what comes next
 The Wild World of AI: 6 Months That Changed Everything
 Agentic Excellence: Mastering AI Agent Evals with Azure AI Evaluation SDK
 Building Multimodal AI Agents From Scratch
 Milliseconds to Magic: Real-Time Workflows Using the Gemini Live API and Pipecat
 RAG in 2025: State of the Art and the Road Forward
 Realtime Conversational Video with Pipecat and Tavus
 Veo 3 for Developers
 Retrieval + Search
 LLM Recommendation Systems (RecSys)
 Blender MCP and The Future Of Creative Tools
 ChatGPT is poorly designed. So I fixed it
 Invisible Users, Invisible Interfaces: Accelerating Design Iteration with AI Simulation
 My AI Thinks I'm Eating My Feelings (and Other Nutritional Insights)
 Text-to-Speech Data Preparation and Fine-tuning Workshop
 The End of Awkward AI Transcriptions
 The Future of Qwen: A Generalist Agent Model
 Navigating AI's Frontier in 2025
 This video was edited with AI agent. But how?
 AI Music Generation, From Prompt to Production
 Giving a Voice to AI Agents
 Unveiling the Latest Gemma Model Advancements
 How to Add Secure Code Interpreting in Your AI App
 Multi model multimodal and multi agent innovations in Azure AI
 Your RAG is Tripping, Here's the Real Reason Why
 E-Values: Evaluating the Values of AI
 Moondream: How Does a Tiny Vision Model Slap So Hard?
 State Space Models for Realtime Multimodal Intelligence
 Second Order Effects of AI
 The Multimodal Future of Education
 The Hierarchy of Needs for Training Dataset Development
 The Era of Unbounded Products: Designing for Multimodal IO
 What's new from Anthropic and what's next
 From Text to Vision to Voice: Exploring Multimodality with OpenAI
 Keynotes & Multimodality Track
 Using AI to Build an Infinite Game
 Storyteller: Building Multi-modal Apps with TypeScript and ModelFusion
 Lessons from the First Viral CLIP App
 The Hidden Life of Embeddings
 AI Engineering 101
 Climbing the Ladder of Abstraction
 The Intelligent Interface
 See, Hear, Speak, Draw